Stream Processing
Streaming data is a continuous sequence of data records generated over time. Stream processing processes records in motion. Unlike batch processing, the engine processes each record immediately upon arrival.
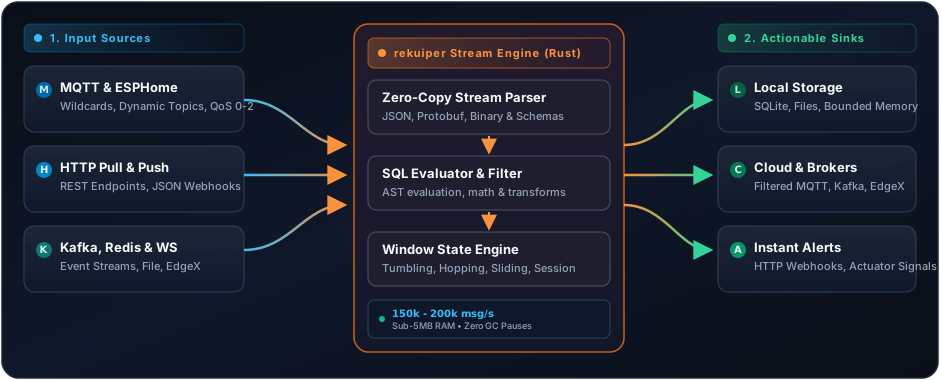
Streaming Characteristics
Stream processing features these primary characteristics:
- Unbounded Data: Streaming data is an infinite dataset that cannot be processed as a static whole.
- Continuous Execution: Because input data is unbounded, processing pipelines run continuously. Workloads distribute evenly over time rather than concentrating in batch intervals.
- Low Latency: Processing records upon generation achieves near real-time response times.
Stream processing unifies operational logic and analytical processing. Systems built on a unified architecture can respond directly to real-time events.
Edge Stream Processing
Edge devices generate telemetry as continuous streams, such as industrial sensor readings.
IoT deployments transmit large volumes of data to cloud infrastructure. Edge stream processing provides these benefits:
- Decreases network bandwidth and cloud transmission costs.
- Reduces raw telemetry volume through local filtering and aggregation.
- Delivers low latency for local control loops.
- Maintains autonomous operations during network disconnections.
Stateful Stream Processing
Stateful stream processing maintains contextual state across multiple events.
Examples of stateful processing include:
- Calculating aggregates such as sum, count, or average across time.
- Detecting changes between sequential events.
- Recognizing patterns across event sequences.
Manage state through these mechanisms: